Lost in Mimicry: Verified Training-Free Post-Editing for LLM Translationese
Abstract
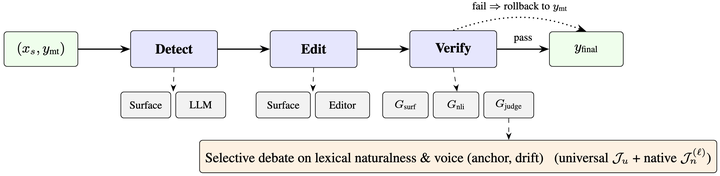
Translations generated by Large Language Models (LLMs) often exhibit unnatural stylistic traces distinct from human-written translations, which we refer to as LLM translationese. We propose MELT, a training-free post-editing framework for mitigating LLM translationese across five target languages (Korean, Chinese, Japanese, German, and French) without weight updates. MELT defines translationese patterns based on faithfulness, voice, register, naturalness, and surface form, and combines a three-stage verification gate with selective multi-agent debate to preserve meaning and mitigate self-bias. Experiments on FLORES-200 show that verification contributes most to quality improvement and that MELT achieves the lowest calibration error with respect to Oracle preference across the five languages. Our analysis further shows that LLM translationese exhibits language-specific realizations while sharing a common mechanism of English-structure mimicry.